A loan processor opens a file that has already been through automated intake, expecting the extracted data to be correct. Instead, the system has identified a 401(k) contribution or tax withholding amount as the borrower’s gross income.
The pay stub is perfectly legible, and the correct figure is right there on the page. The problem is that the document’s layout differs from what the system was configured to recognize. Someone must now review the file and correct the data that automation was intended to capture.
This scenario illustrates a recurring challenge in mortgage document processing. The same document type can look different depending on the lender, financial institution, payroll provider, or loan program. When document processing relies heavily on fixed layouts, these variations can require additional configuration, template maintenance, or manual intervention.
The underlying issue is how a system identifies and interprets information on a page. Understanding the difference between zonal Optical Character Recognition (OCR) and templateless Intelligent Document Processing (IDP) helps explain why this distinction matters for modern mortgage operations.
What Is the Difference Between Zonal OCR and Template-Free IDP?
Zonal OCR extracts information from predefined areas of a document. These areas are configured around an expected layout, making the approach useful when documents follow consistent formats. However, changes in field positions or page structure can require template adjustments.
Template-free IDP takes a different approach.
Using AI and machine learning, it can identify and extract relevant information from documents without relying on fixed coordinates or extensive template configuration. This makes it better suited to processing documents that vary in format and structure.
The distinction is not simply about how quickly text is extracted. It is also about how flexibly a system can process different document layouts and identify the information needed for a business workflow.
| Dimension | Zonal OCR | Template-Free IDP |
|---|---|---|
| Data location | Relies on predefined zones | Uses document content, patterns, and context |
| New or unfamiliar formats | May require template updates | Can reduce the need for new templates |
| Layout variations | Sensitive to changes in field positions | More adaptable to variations in document structure |
| Extraction errors | Can extract incorrect values when layouts differ | AI-driven extraction and validation can help improve data quality |
| Document classification | May require a separate classification process | Can combine classification and extraction within an IDP workflow |
| Multi-page documents | May depend on configured page structures | Can accommodate varying document structures, depending on the solution |
| Configuration and maintenance | May require ongoing template management | Reduces dependence on template creation and maintenance |
The practical difference becomes apparent when a document does not match an expected layout. A zonal OCR system may fail to locate a field or extract an incorrect value from an unexpected position. Template-free IDP offers greater flexibility by using AI and machine learning to identify relevant information across varying document formats.
Where Traditional OCR Can Fall Short on Mortgage Documents
Mortgage document processing involves a wide variety of financial records, disclosures, supporting documents, and loan-specific forms. Even documents belonging to the same category can vary significantly depending on their source.
Several challenges make fixed-template approaches difficult to maintain at scale.
- Varying formats: Lenders, investors, payroll providers, and financial institutions may present similar information in different layouts. Profit and Loss (P&L) statements, business tax returns, and Verification of Employment (VOE) documents can all contain variations in field placement and structure.
- Variable page counts: Loan-specific riders and addenda, including adjustable-rate mortgage (ARM) and planned unit development (PUD) documents, can change the length and structure of a document package.
- Inconsistent scan quality: Skewed pages, low-resolution scans, and handwritten annotations can make information harder to recognize and extract reliably.
- Multiple document sources: A single loan file may contain documents from several institutions, each with different formatting conventions and information structures.
Consider a bank statement from a regional credit union where the running balance appears in a different column from the one expected by a predefined template. A system configured around another bank’s layout may struggle to locate the correct value, even though the information is clearly visible to a human reviewer.
These variations can create a cycle of template updates, testing, and manual corrections. As document volumes and source diversity increase, maintaining these configurations can add complexity to mortgage operations.
Extracting Data from a Complex Loan File Without Relying on Fixed Templates
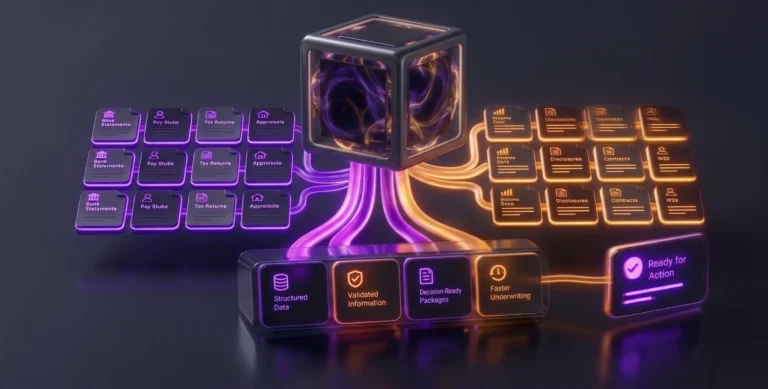
A complex mortgage loan file rarely consists of a single document. It may contain financial statements, income records, bank statements, tax returns, disclosures, and supporting documents collected from different sources.
Template-free IDP helps address this complexity by using AI and machine learning to classify documents and identify relevant information without depending entirely on predefined layouts.
Across a mortgage document workflow, this can support several activities:
- Document classification: Identifying document types, such as pay stubs, bank statements, and tax returns, to support downstream processing.
- Context-aware extraction: Identifying relevant information from document content and patterns rather than relying exclusively on fixed coordinates.
- Processing layout variations: Reducing dependence on rigid templates when documents differ in formatting or structure.
- Data validation: Applying validation checks to help identify missing, inconsistent, or potentially incorrect information for further review.
Together, these capabilities can help mortgage teams process varied document packages more efficiently and reduce the manual effort associated with repetitive document handling.
For example, a borrower’s income may appear as a clearly labeled amount on one pay stub but require closer examination of several line items on another. A flexible extraction approach can help identify the relevant information across different layouts, while validation checks can help flag discrepancies that require attention.
Automation does not eliminate the need for oversight. Mortgage processing involves financial information that must be handled carefully. Combining automated extraction with appropriate validation and human review helps teams address exceptions while reducing the need to review every document manually.
Why DocVu.AI?
DocVu.AI is an AI- and machine learning-powered Intelligent Document Processing platform designed to help organizations automate document-intensive workflows. Its capabilities include document classification, data extraction, validation, and template-free processing.
In mortgage operations, these capabilities can help lenders manage the variety and volume of documents involved in loan processing. Rather than relying solely on rigid document layouts, DocVu.AI uses intelligent processing capabilities to identify and extract relevant information from documents with varying formats and structures.
DocVu.AI supports mortgage workflows across loan origination, application, approval, closing, and servicing. Its document processing capabilities help lenders streamline document handling, improve operational efficiency, and support faster mortgage processing.
By reducing dependence on manual document handling and repetitive template maintenance, template-free IDP can help mortgage teams focus their attention on exceptions, verification, and other activities that require human judgment.
To learn more about DocVu.AI’s approach to intelligent document processing, explore our website DocVu.AI website.
Frequently Asked Questions
Dynamic layout document processing refers to processing documents that may vary in structure or formatting without relying exclusively on a fixed template for each variation. AI-powered IDP can help identify and extract relevant information across different layouts, reducing the need for repetitive template configuration.
Mortgage document classification AI uses artificial intelligence and machine learning to identify the type of document being processed, such as a pay stub, bank statement, or tax return. Classification helps organize documents and supports subsequent extraction and processing activities.
Unstructured document extraction involves identifying relevant information in documents that do not follow a consistent, predefined structure. In mortgage processing, this may include narrative letters, legal agreements, and other supporting documents.
Semi-structured documents, such as pay stubs, bank statements, and tax returns, may contain recognizable labels or fields but vary in layout. AI-powered IDP can help process both structured and less structured information, depending on the document and workflow.
Yes. OCR can still be used to recognize text in documents. Template-free IDP extends the process by applying AI and machine learning techniques to classify documents, identify relevant information, and support extraction without relying exclusively on predefined field coordinates.
No. Template-free IDP can reduce manual effort by automating document classification and data extraction. However, validation, exception handling, and human review may still be necessary for incomplete, inconsistent, or uncertain information.
Template-free IDP uses AI and machine learning to identify and extract relevant information without depending entirely on predefined templates. This can make it more adaptable to unfamiliar layouts and reduce the need for manual template creation. Results depend on the document, the information being extracted, and the capabilities of the processing solution.
Conclusion
MSR portfolio transfers require careful coordination of loan documentation, data, and servicing information. As portfolios grow and document formats vary, manual processing can create additional demands on operational teams.
AI-powered document ingestion offers a way to streamline document classification, indexing, extraction, and validation. By helping organize loan records and identify potential discrepancies, automation can support more efficient onboarding while allowing servicing professionals to focus on exceptions and decisions that require human oversight.
With intelligent document processing capabilities from DocVu.AI, mortgage organizations can explore a more structured approach to document-intensive workflows and strengthen the processes that support mortgage servicing operations.